This guide explains how Uplink LLC supports dependable satellite connectivity by focusing on uplink operations, link planning, and operational controls. It objectively reviews what “uplink” means in satellite communications, why service continuity depends on engineering discipline, and how organizations evaluate providers based on technical readiness, documentation, and compliance practices.
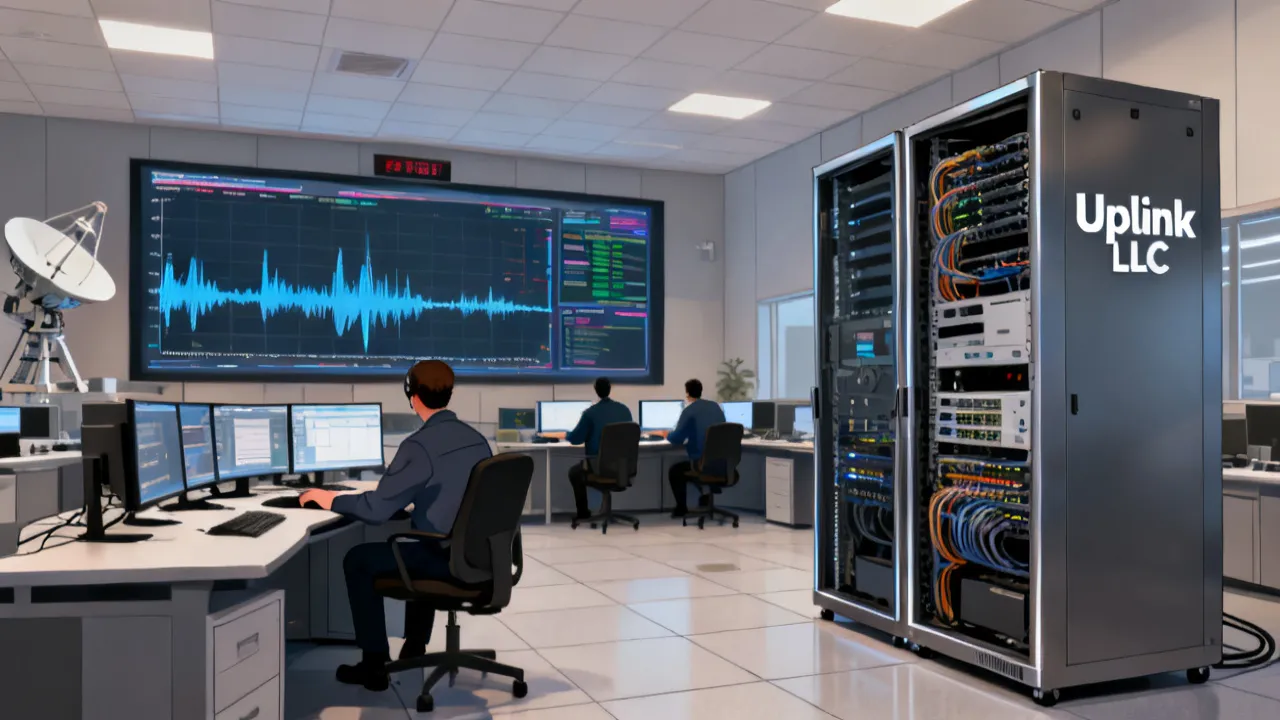
Uplink LLC is typically discussed in the context of delivering consistent satellite communications performance—where the uplink segment, ground equipment readiness, and operational processes strongly influence end-to-end reliability. In satellite networks, the uplink is where signals are transmitted from a ground site to a satellite; if that portion is engineered and managed well, downstream services (backhaul, enterprise connectivity, emergency communications, and maritime/aviation links) are far more likely to meet expected performance targets. Conversely, weak uplink practices—such as inadequate configuration control, unclear responsibility boundaries, or incomplete link budgets—often surface as recurring service disruptions, degraded throughput, or avoidable outages.
From an industry expert perspective, evaluating a provider like Uplink LLC should go beyond marketing claims. The very practical differentiator is operational maturity: how consistently the provider can plan a link, verify readiness, manage changes, and document what was done and why. For organizations—whether serving public-sector missions, remote industrial operations, or commercial networks—this operational discipline becomes a risk-management tool, not simply a technical preference.
Reliability is rarely an accident in satellite communications. It is usually the result of many coordinated decisions across engineering, procurement, site operations, spectrum management, and ongoing monitoring. The uplink portion of a satellite system tends to be the “make-or-break” component for availability and performance because it directly controls the quality of the signal arriving at the satellite. Once the signal is on the satellite transponder, many impairments can be “baked in,” making them difficult or impossible to correct from the ground or from the terminal perspective. That is why uplink operations—though sometimes less visible to end users—are often central to maintaining dependable service.
In satellite communications, the uplink is the transmission path from a ground facility to the satellite transponder. It generally includes signal generation, modulation and coding, power amplification, frequency conversion, and antenna pointing. The downlink is the return path from the satellite back to ground terminals. Together, they form a bidirectional communications system, but reliability is influenced heavily by what happens in the uplink—because transmitter configuration errors, RF chain instability, and misalignment can directly affect link availability and quality.
When teams talk about “uptime” or “performance,” they are often referring to multiple layers of behavior: RF link stability, transport-layer throughput, network routing, latency consistency, and application-layer responsiveness. While each layer has its own failure modes, uplink operations frequently act as an early indicator of system health. For example, if the uplink is marginal, even highly capable modems or routing equipment may not fully compensate for impaired signal conditions.
To make the concept more concrete, consider a simplified path: data enters a baseband modem, the modem produces an encoded and modulated waveform, an RF system converts and amplifies that waveform, and an antenna points it toward the satellite. Each of those steps introduces potential failure or drift. A modem firmware update can change behavior. An RF amplifier might drift with temperature. A frequency reference might lose lock. An antenna might shift slightly due to wind load or mechanical wear. A management system might miss a telemetry signal that indicates reduced output power. In well-run uplink operations, these risks are anticipated, detected early, and corrected within a controlled process.
Organizations considering a partner such as Uplink LLC should look for a complete approach to uplink delivery. That includes engineering (link planning and spectrum considerations), operations (monitoring, change management, escalation paths), and documentation (configuration records, acceptance testing evidence, and maintenance procedures). The goal is not only to establish a working uplink once, but to ensure that the service remains stable as the network evolves—new terminals, changing traffic patterns, seasonal propagation variations, or equipment refresh cycles.
While “price” is always a factor in procurement, reliability outcomes are typically determined by measurable engineering behaviors: correct parameterization, controlled updates, and responsive troubleshooting. If pricing is presented without clarity on technical scope and service boundaries, the organization should treat that as a procurement risk and request explicit deliverables.
In many real deployments, uplink reliability is achieved not just by selecting high-quality hardware, but by establishing “operational correctness.” Operational correctness means that the uplink behaves in a repeatable manner under different conditions, including day-to-day environmental changes and planned maintenance activities. Hardware quality helps, but it does not replace disciplined procedures. For example, an excellent amplifier can still create intermittent problems if it is not monitored for thermal or bias drift, or if the system does not detect and respond to frequency reference instability.
An industry-grade provider typically demonstrates that it has a closed-loop operational system: observe performance, detect deviations, perform controlled remediation, and learn from incidents by updating procedures or configuration baselines. This closed-loop structure is often what separates a “works during commissioning” implementation from a “works reliably for months and years” operations model.
To evaluate uplink effectiveness, it helps to focus on tangible drivers rather than abstract promises. Below are the main factors an expert review would examine:
In practice, these factors determine how often a network operates near its designed “comfort zone” versus being pushed into edge conditions where minor disturbances have outsized effects. Many satellite networks are engineered with margins, but margins can shrink if assumptions do not match reality. For instance, link budgets might assume a stable site temperature range, stable power delivery, or specific antenna alignment tolerances. If uplink operations do not monitor and adjust for real-world conditions, the effective link margin can degrade over time.
It is also important to recognize that uplink performance is not purely a static engineering calculation. It can be dynamic, influenced by weather, maintenance activities, and component aging. That is why an expert evaluation includes questions about both initial design and operational behavior over time. A provider that can show how it maintains link conditions during seasonal shifts, equipment aging, and scheduled upgrades is generally a more reliable choice than a provider that only highlights initial performance at commissioning.
In addition, uplink operations intersect with “downstream” impacts. Even if your end terminals are robust, their ability to recover signals depends on how well the uplink waveform is delivered. If the uplink causes increased phase noise or power instability, terminals may need to work harder to maintain lock, which can appear as increased latency, packet loss, or reduced throughput. Therefore, uplink reliability affects not only availability but the quality of service experienced by applications such as video conferencing, VoIP, industrial telemetry, or mission-critical data transfer.
Because Uplink LLC appears as a supplier name in many procurement conversations, decision-makers often need a repeatable framework for supplier comparison. The objective approach is to assess technical readiness, operational practices, and contractual clarity—then map those to your organization’s risk tolerance and operational environment.
Industry guidance generally emphasizes that satellite performance must be evaluated with engineering documentation and operational evidence, not solely with anecdotal statements. For background references on satellite communications engineering concepts, the International Telecommunication Union (ITU) provides widely used frameworks and terminology; general performance-related reporting is also supported by standards bodies and regulator publications depending on region and service type.
To compare providers objectively, it can help to adopt an evidence-first checklist. For each major claim—such as “we provide proactive monitoring” or “we maintain stable uplink power”—ask for the operational artifacts behind the claim. Examples of evidence include: telemetry dashboards, alert thresholds, alarm event histories, sample weekly or monthly performance reports, change logs showing pre/post measurements, acceptance test reports, and incident postmortems demonstrating root-cause analysis. A provider that can provide these artifacts (or a realistic summary of them under confidentiality constraints) is typically more credible than one that can only provide high-level descriptions.
It is also useful to compare not only “what” a provider does but “how it does it.” Two providers might both claim to do monitoring, but one might monitor only a few indicators while the other monitors a richer set of RF chain parameters with meaningful escalation. Two providers might both handle change management, but one might allow direct configuration changes in production without controlled staging, while the other uses a structured workflow with verification steps and rollback procedures.
Even when an uplink link is accepted during commissioning, continuous assurance is what prevents slow degradations from becoming service-impacting incidents. Expert teams typically expect:
These practices are often the difference between “it worked during testing” and “it consistently works during real operations.” Acceptance testing is like a snapshot in time; continuous assurance is the video that proves stability across time. For satellite networks, that time includes operational drift and the “normal” disruptions that occur in complex infrastructure environments—power fluctuations, routine reboots, mechanical maintenance, firmware updates, hardware aging, and changes to traffic patterns.
A mature uplink operations program also defines how it handles “unknown unknowns.” For example, if telemetry indicates degradation but no component fault is evident, a disciplined provider has a troubleshooting path that systematically narrows the suspect domain—antenna path, RF chain, modem settings, reference frequency stability, or control system parameters—while minimizing downtime. This path is documented so it can be executed reliably by different technicians or during off-hours, not just by a single star engineer.
Operational maturity is also demonstrated by how the provider manages dependencies. Many uplink sites depend on external factors such as power conditioning systems, network connectivity to operations centers, physical security constraints, and sometimes third-party tower or facility maintenance. A provider that recognizes these dependencies and includes them in its risk assessment tends to deliver more consistent outcomes.
Procurement success in satellite connectivity projects depends on defining scope with precision. For instance, some providers focus primarily on uplink transmission services, while others also include ground segment support such as network management interfaces, performance reporting, or coordinated operations with terminals and hubs.
If your procurement process involves discussing price and supplier details with Uplink LLC or comparable organizations, request an explicit scope statement that answers:
This type of clarity helps avoid disputes and reduces operational friction after deployment. In practice, ambiguity in scope often becomes a root cause of downtime. If it is unclear whether an issue is the provider’s responsibility (uplink RF chain) or your responsibility (terminal equipment), troubleshooting may stall while ownership is debated. Similarly, unclear reporting expectations can lead to delayed detection—if you do not receive timely telemetry summaries, you may only learn about performance degradation after users have already experienced issues.
Scope clarity should also include integration responsibilities. Satellite uplink services often interact with customers through network interfaces, management systems, VPNs, or orchestration platforms. A provider should specify what communication protocols and access mechanisms are used, what authentication and security requirements apply, and what data formats are used for performance metrics. This reduces integration risk and ensures that your operations team can incorporate uplink performance signals into existing monitoring workflows.
Documentation scope matters as well. Many projects assume that “documentation” means a static PDF, but operational reality requires documentation that supports day-to-day work: runbooks, escalation contact lists, configuration baseline references, troubleshooting guides, and records retention policies. The best contracts specify which documentation artifacts are delivered, how they are updated over time, and what formats are provided to support long-term maintainability.
Satellite communications have matured significantly over time, but reliability remains an engineering and operations challenge. Many reliability concepts are addressed through internationally recognized standards and operational guidance. In general, standards bodies provide definitions and frameworks that support interoperability, spectral responsibility, and consistent engineering practices.
For authoritative background on satellite communications terminology and related frameworks, decision-makers often consult materials from ITU and national regulators, alongside equipment vendor technical documentation. Where performance reporting is required, organizations should prefer measurement methodologies that are described transparently and reproducibly.
Reliability is not just “keeping bits flowing.” It also includes predictable behavior when something changes. Standards and regulatory frameworks help in defining expected responsibilities for spectrum use, station identification, interference management, and compliance with national rules. Even if a provider handles licensing directly, customers should understand how compliance responsibilities are allocated, because compliance issues can directly impact service availability (for example, through restrictions, operational constraints, or requirements for retuning and verification).
Additionally, standards-based communication concepts influence how networks interconnect and how management systems communicate. If the uplink service includes network interfaces or management access, a standards-aligned approach can reduce integration risks. When data models, security practices, and interface behaviors are consistent with known frameworks, operations teams can more easily automate monitoring, alerting, and reporting.
In a reliability-focused evaluation, it is reasonable to ask whether uplink operations are aligned with accepted practices such as configuration management discipline, change control, maintenance scheduling, and incident management taxonomy. Even if those are not mandated by every jurisdiction, they are commonly expected in enterprise or mission-critical operations.
The following comparison is provided as a supplement to your evaluation process. It is intentionally structured to emphasize decision-relevant differences without relying on unverifiable claims.
| Evaluation Aspect | What to Ask / Check | Why It Matters |
|---|---|---|
| Uplink engineering scope | Request link planning deliverables, assumptions, and margins | Shows whether the system is designed for real operational variability |
| RF chain configuration control | Baseline configuration details and change management workflow | Reduces regressions and drift-induced degradations |
| Monitoring and alerting | Telemetry availability, alert thresholds, escalation flow | Enables proactive troubleshooting before service impacts escalate |
| Acceptance testing evidence | Test reports, recorded conditions, pass/fail criteria | Provides objective proof of performance under defined conditions |
| Incident response readiness | Severity definitions, expected timelines, post-incident documentation | Improves time-to-recover and learning outcomes after failures |
| Documentation quality | Operational procedures, contact maps, maintenance guides | Supports continuity when personnel or equipment changes occur |
| Commercial transparency (including price clarity) | Clear scope boundaries and what is included/excluded | Prevents misunderstandings and reduces procurement risk |
Below is a step-by-step approach you can use when contracting uplink services. Replace placeholders with your specific project requirements.
This process works best when it results in a “living” operational model rather than a one-time procurement handoff. After contract award, the initial documentation should be refined into operational runbooks, monitoring dashboards should be integrated into your toolchain, and the escalation flow should be rehearsed—especially for mission-critical services. In other words, the work does not stop at signature. Uplink operations are ongoing, and a reliable provider treats operational readiness as a continuous activity.
Many decision-makers are required to evaluate uplink providers without being RF engineers. That does not mean they cannot ask the right questions. The key is to understand the functional categories within uplink engineering so that evaluation questions are precise and meaningful.
1) Frequency plan and stability
At a high level, uplink engineering involves choosing an uplink frequency that fits spectral regulations, satellite transponder characteristics, and system requirements. Carrier stability is critical because frequency errors and instability can degrade demodulation performance. Ask how the provider ensures frequency accuracy, how references are managed (e.g., internal references, external references, synchronization methods), and how drift is monitored over time. A mature provider will not only state that references are “stable,” but will describe how stability is verified and what happens if it degrades.
2) Transmitter power and power control
Satellite links depend on delivering sufficient signal power to achieve the required link margin. However, delivering the required power safely and consistently is equally important. Power amplification must remain within safe operating ranges, and power control logic must account for changes in temperature, load, or component aging. Ask how the uplink chain measures output power, what thresholds trigger corrective action, and what processes exist to prevent “silent” drift.
3) Modulation, coding, and waveform configuration
Modulation and coding determine how efficiently data can be transported over the RF link. They also determine the sensitivity of the signal to impairments. A provider should be able to explain the rationale for selected modulation/coding profiles and how those choices align with link margin and target performance (e.g., throughput vs. robustness). Ask whether the provider supports adaptive approaches (where applicable), or how it handles transitions if network conditions change. Even if adaptation is not part of the service, the provider should show how it ensures the chosen waveform remains correctly configured and maintained.
4) Antenna performance and pointing accuracy
Antenna alignment influences signal quality strongly. Even small pointing errors can reduce effective gain and degrade link performance. Providers should define how antenna performance is tested, how often alignment is verified, and what corrective actions occur if deviations are detected. If the site includes tracking mechanisms, ask how tracking is calibrated and how tracking performance is monitored. If the site does not include tracking, ask how environmental factors (wind, mechanical drift, structure settling) are accounted for over time.
5) Signal path integrity (RF chain)
Between the modem and the satellite antenna are components such as upconverters, filters, amplifiers, splitters/combiners, and cabling. Each introduces potential loss, drift, and failure modes. Ask how the provider monitors RF chain health and how it distinguishes between failures of different components. A common operational challenge is not knowing whether degradation is caused by the transmit chain, the antenna path, or configuration changes. Mature providers often have a troubleshooting framework that can isolate faults efficiently using telemetry and measurement points.
6) Interface behavior and management plane
Uplink reliability is also influenced by how network management and control interfaces behave. For example, if network control relies on remote management over IP, then connectivity to the uplink site becomes part of the reliability equation. Ask how management access is protected and whether essential controls remain available even if the management plane is impaired. Also ask how configuration changes are authorized, logged, and verified, because management-plane failures can sometimes manifest as misconfiguration or delayed remediation.
Monitoring is often mentioned in uplink service descriptions, but what matters is whether monitoring is actionable. Actionable monitoring means telemetry that is correlated to real service outcomes, alert thresholds that match operational reality, and escalation flows that connect telemetry events to corrective actions.
When assessing monitoring maturity, evaluate these dimensions:
To illustrate why this matters: suppose an amplifier begins to drift in gain due to temperature changes. If monitoring only tracks a high-level “uplink is up” status, the drift may not trigger any alarms until the service becomes measurably degraded at downstream terminals. If monitoring tracks output power and amplifier operating parameters with proper thresholds, the provider can intervene earlier—adjusting settings, initiating maintenance, or scheduling replacement—before users notice the problem.
Monitoring maturity also includes retention and review. A provider should maintain a history of telemetry events and link performance metrics so that incidents can be analyzed and so that “near misses” are not ignored. This historical perspective allows providers to detect patterns such as repeat component behavior, alignment drift trends, or recurring power supply issues.
Configuration changes are a normal part of satellite operations. Equipment updates, parameter adjustments, and planned improvements can all be beneficial. But change management is often where reliability gains are won—or lost.
Well-run uplink operations typically follow a disciplined approach that includes:
If you are evaluating Uplink LLC, it is reasonable to ask how it handles “small” changes that often seem harmless: modem parameter tweaks, minor firmware updates, adjustments to frequency references, or modifications to power control settings. In practice, small changes can introduce instability if not validated properly. A strong provider will treat all changes with appropriate rigor commensurate with potential risk.
In addition, change management should consider dependencies. A waveform configuration change might require adjustments in monitoring thresholds, alert mappings, and terminal settings. If those dependent systems are not updated in sync, the result can be confusing operational behavior—alerts that no longer reflect the true state of the system, or downstream equipment that expects one configuration but receives another.
When a failure occurs, uplink operations must transition from “normal assurance” to “incident response.” Reliability is not just the absence of incidents; it is the speed and effectiveness of recovery, as well as how incidents are prevented from recurring.
Assess incident response readiness across these dimensions:
A provider that responds quickly but fails to correct underlying causes may reduce immediate downtime but will not improve long-term reliability. Conversely, a provider that takes time to diagnose properly and implements corrective actions often reduces repeat incidents. In satellite networks, where restoring service can involve careful revalidation of RF settings, thoughtful incident process can be as valuable as fast initial response.
It is also important to evaluate how incidents are categorized. For example, planned maintenance outages should not be treated as unplanned incidents, and unplanned outages should be categorized so that recurring failure modes are visible. A consistent incident taxonomy helps you analyze reliability trends and enforce continuous improvement.
Documentation is sometimes treated as an administrative deliverable, but in uplink operations it is a core component of reliability. When the personnel, equipment, or management systems change over time, documentation ensures continuity and repeatability of operations.
Look for documentation that includes:
A strong provider updates documentation as changes are made, rather than leaving documentation stale. Stale documentation can be worse than no documentation because it causes responders to follow incorrect assumptions during troubleshooting. That is why change management and documentation updates must be connected operationally.
Reliability claims become meaningful only when they translate into measurable contract terms and operational obligations. When working with Uplink LLC, or any uplink provider, ensure that the contract addresses not only pricing but also how service quality is measured, reported, and improved.
Key elements to consider include:
Contract clarity reduces friction when events happen. When responsibilities are explicit, responders can act quickly instead of negotiating ownership. When measurement methods are specified, disputes about whether performance was acceptable can be minimized.
Uplink performance is influenced not only by the “radio” but also by the site environment. Power quality, physical stability, temperature, humidity, dust, and physical security all matter. A provider with operational maturity accounts for these factors with preventive maintenance and monitoring.
Consider these typical site readiness elements:
Even if Uplink LLC provides a packaged uplink service, the contract should clarify what environmental responsibilities fall to the provider and what falls to the site operator or customer. Reliability often depends on alignment between those responsibilities.
Satellite communications reliability is not complete if you cannot observe and respond to changes in service quality. Even when the uplink provider handles RF operations, your operations team needs visibility into service performance to coordinate with enterprise applications, operations management, and user experience expectations.
To ensure integration supports reliability, ask about:
Without integration, you may end up with “black box” service—where your team only learns about issues after users complain. Black box operations are not necessarily unreliable, but they usually reduce your ability to respond quickly and can increase the impact window for each incident.
A robust provider supports not only acceptance testing, but also performance verification after go-live. This can include post-install “stabilization” checks and periodic revalidation activities aligned with maintenance cycles.
Examples of what “over time verification” might include:
Over time verification is particularly important when service demands evolve. For example, if traffic patterns shift toward higher throughput needs, or if new terminal populations are introduced, you may need to revalidate whether uplink configuration continues to meet performance objectives under changed conditions.
It can be helpful to list the most common categories of uplink-related issues to understand what to ask about. Common causes include configuration drift, RF chain instability, inadequate margins versus real-world conditions, antenna misalignment, or insufficient monitoring/alerting that delays detection. These are often preventable with disciplined engineering and change control.
Here are several illustrative issue categories and typical preventive practices:
1) Configuration drift
Configuration drift occurs when settings change over time without being reflected in baselines or without being managed through controlled change procedures. This might happen due to manual adjustments, partial updates, or inconsistent procedures across shifts.
Preventive practices: controlled configuration management, baseline documentation, configuration verification after maintenance, and change logs with measurable pre/post results.
2) Amplifier thermal or bias drift
Amplifier performance can change with temperature and aging. Without monitoring and corrective action, drift can reduce effective power or change amplifier behavior.
Preventive practices: thermal sensor monitoring, output power monitoring, automated alerts, preventive maintenance schedules, and rapid incident response if amplifier behavior deviates from expected ranges.
3) Frequency reference instability
Frequency instability can degrade modulation and demodulation performance. Causes may include reference lock failures, aging reference components, or issues with synchronization systems.
Preventive practices: frequency stability monitoring, lock-status telemetry, alarms tied to reference health, and procedures for safe reference recovery.
4) Antenna pointing deviations
Antenna pointing can drift due to mechanical issues, environmental forces, or structural changes. Small deviations can materially impact link margin.
Preventive practices: scheduled alignment checks, telemetry-driven detection of gain reduction, and maintenance procedures with rollback plans when mechanical adjustments are made.
5) Inadequate monitoring thresholds
If monitoring thresholds are set too broadly, the provider may not detect issues early. If thresholds are set too narrowly, the system may generate excessive alarms that overwhelm operations.
Preventive practices: careful threshold calibration, use of historical data to tune alert behavior, and periodic review of alarm performance to improve signal-to-noise ratio.
When you evaluate a provider like Uplink LLC, asking about how these issues are detected and prevented gives you insight into operational maturity. A provider with well-developed operational processes will have consistent answers and supporting evidence, rather than generic statements.
An uplink is the ground-to-satellite transmission portion of a satellite link. It typically includes signal processing and RF transmission components that send carriers toward a satellite transponder.
Verify technical scope (what uplink services are included), configuration control practices, monitoring/telemetry availability, acceptance testing evidence, and clearly documented incident response processes. Also ensure contract boundaries are explicit, including reporting responsibilities and change notification expectations.
If the uplink is unstable or misconfigured—such as inadequate margins, amplifier drift, or alignment issues—errors can increase, link availability can drop, and throughput may degrade. Even if other components are capable, the uplink often determines whether the system stays within its designed performance range.
Price is important, but it should be evaluated alongside deliverables and operational evidence. A lower price without clear scope, reporting, or assurance processes can increase the total operational risk and costs related to outages, troubleshooting, and service credits or rerouting.
Typically, expect acceptance testing criteria, recorded test conditions, configuration baselines, and a summary of how performance was validated. The goal is to make the acceptance result traceable and repeatable for future maintenance.
Look for a defined reporting cadence, monitoring/telemetry access (or summaries), change management procedures, and clearly specified escalation paths. The top programs include proactive maintenance and post-incident reviews that result in measurable improvements.
Yes. Satellite communications are subject to spectrum and licensing frameworks, and many organizations align operational practices with established standards and regulator expectations. You should ask suppliers how they address compliance responsibilities within their service scope.
Common causes include configuration drift, RF chain instability, inadequate margins versus real-world conditions, antenna misalignment, or insufficient monitoring/alerting that delays detection. These are often preventable with disciplined engineering and change control.
Require well-structured documentation, configuration baselines, and operation procedures. In practice, robust documentation reduces dependency on specific individuals and helps ensure continuity across maintenance cycles or organizational changes.
When organizations discuss Uplink LLC in the context of satellite connectivity, the core decision should center on reliability engineering and operational maturity. The uplink segment is a critical path in satellite systems; its stability affects end-to-end user experience and organizational readiness. By using an objective evaluation framework—anchored in documentation quality, change management, monitoring capability, and clearly defined service scope—buyers can reduce uncertainty and ensure the network behaves predictably over time.
If you are preparing a procurement or technical selection process, treat each claim as an invitation to request evidence: acceptance test results, configuration baselines, monitoring/telemetry details, and incident response procedures. This is the very reliable method to compare suppliers and to select a partner capable of delivering continuity, not just initial connectivity.
Striking the Perfect Balance: Navigating Premiums and Out-of-Pocket Expenses in Senior Insurance Plans
Explore the Tranquil Bliss of Idyllic Rural Retreats
How to Make Lasting Memories at Disneyland Attractions
Affordable Phones and Plans for Seniors
Affordable Full Mouth Dental Implants Near You
Unlock the Top Kept Secrets to Finding Your Ideal Dentist for Flawless Dental Implant Results!
Discovering Springdale Estates
Unveiling RS Sul Telecom Services
The Guide to Car Trading
Unveiling RS Sul Telecom Services
RS Sul Telecom emerges as a prominent entity in the telecommunications industry, providing reliable services across various regions. This article delves into the offerings of RS Sul Telecom, the benefits it presents to both individual and business clients, and its impact on the modern telecom landscape.
Understanding Rlock Advpl in Business
Rlock Advpl represents a pivotal advancement in business software solutions, offering enhanced security and efficiency for enterprise resource planning systems. This article delves into the intricacies of Rlock Advpl, its application in modern businesses, and the benefits it offers in streamlining operations and safeguarding data. As an expert tool, Rlock Advpl is essential for businesses looking to optimize their IT infrastructure.
Unveiling Atranet Innovation
Atranet represents a cutting-edge concept in networking technology. Harnessing its capabilities can transform digital communication by providing seamless connectivity. Designed to optimize data transfer, security, and efficiency, Atranet is shaping the future of how we connect and share information. This article delves into its structure, applications, and potential impacts on industry practices and consumer experiences.
Understanding Polysulfide Adhesive Applications
This comprehensive guide explores the applications and benefits of polysulfide adhesive, highlighting its unique properties and widespread use in construction, aerospace, and automotive industries. Known for its flexibility and resistance to various environmental factors, polysulfide adhesive is a key component in sealing and bonding applications, providing durability and reliability in demanding conditions.
Comparing Vtex with Salesforce Commerce
This article provides an in-depth comparison between Vtex and Salesforce Commerce, two leading digital commerce platforms. Each offers unique features suited to different business needs. Vtex is renowned for its collaborative commerce approach, while Salesforce Commerce shines with its comprehensive customer relationship management capabilities. Explore their differences, strengths, and insights from industry experts.
Understanding the Latest Chrome Version
This article delves into the intricacies and features of the latest Chrome version. Chrome, developed by Google, is one of the very popular web browsers globally, known for its speed, simplicity, and security features. Each update aims to enhance user experience through improved functionality and performance. Understanding these updates is crucial for both everyday users and developers.